zega
An embeddable graph database. Written in Rust.
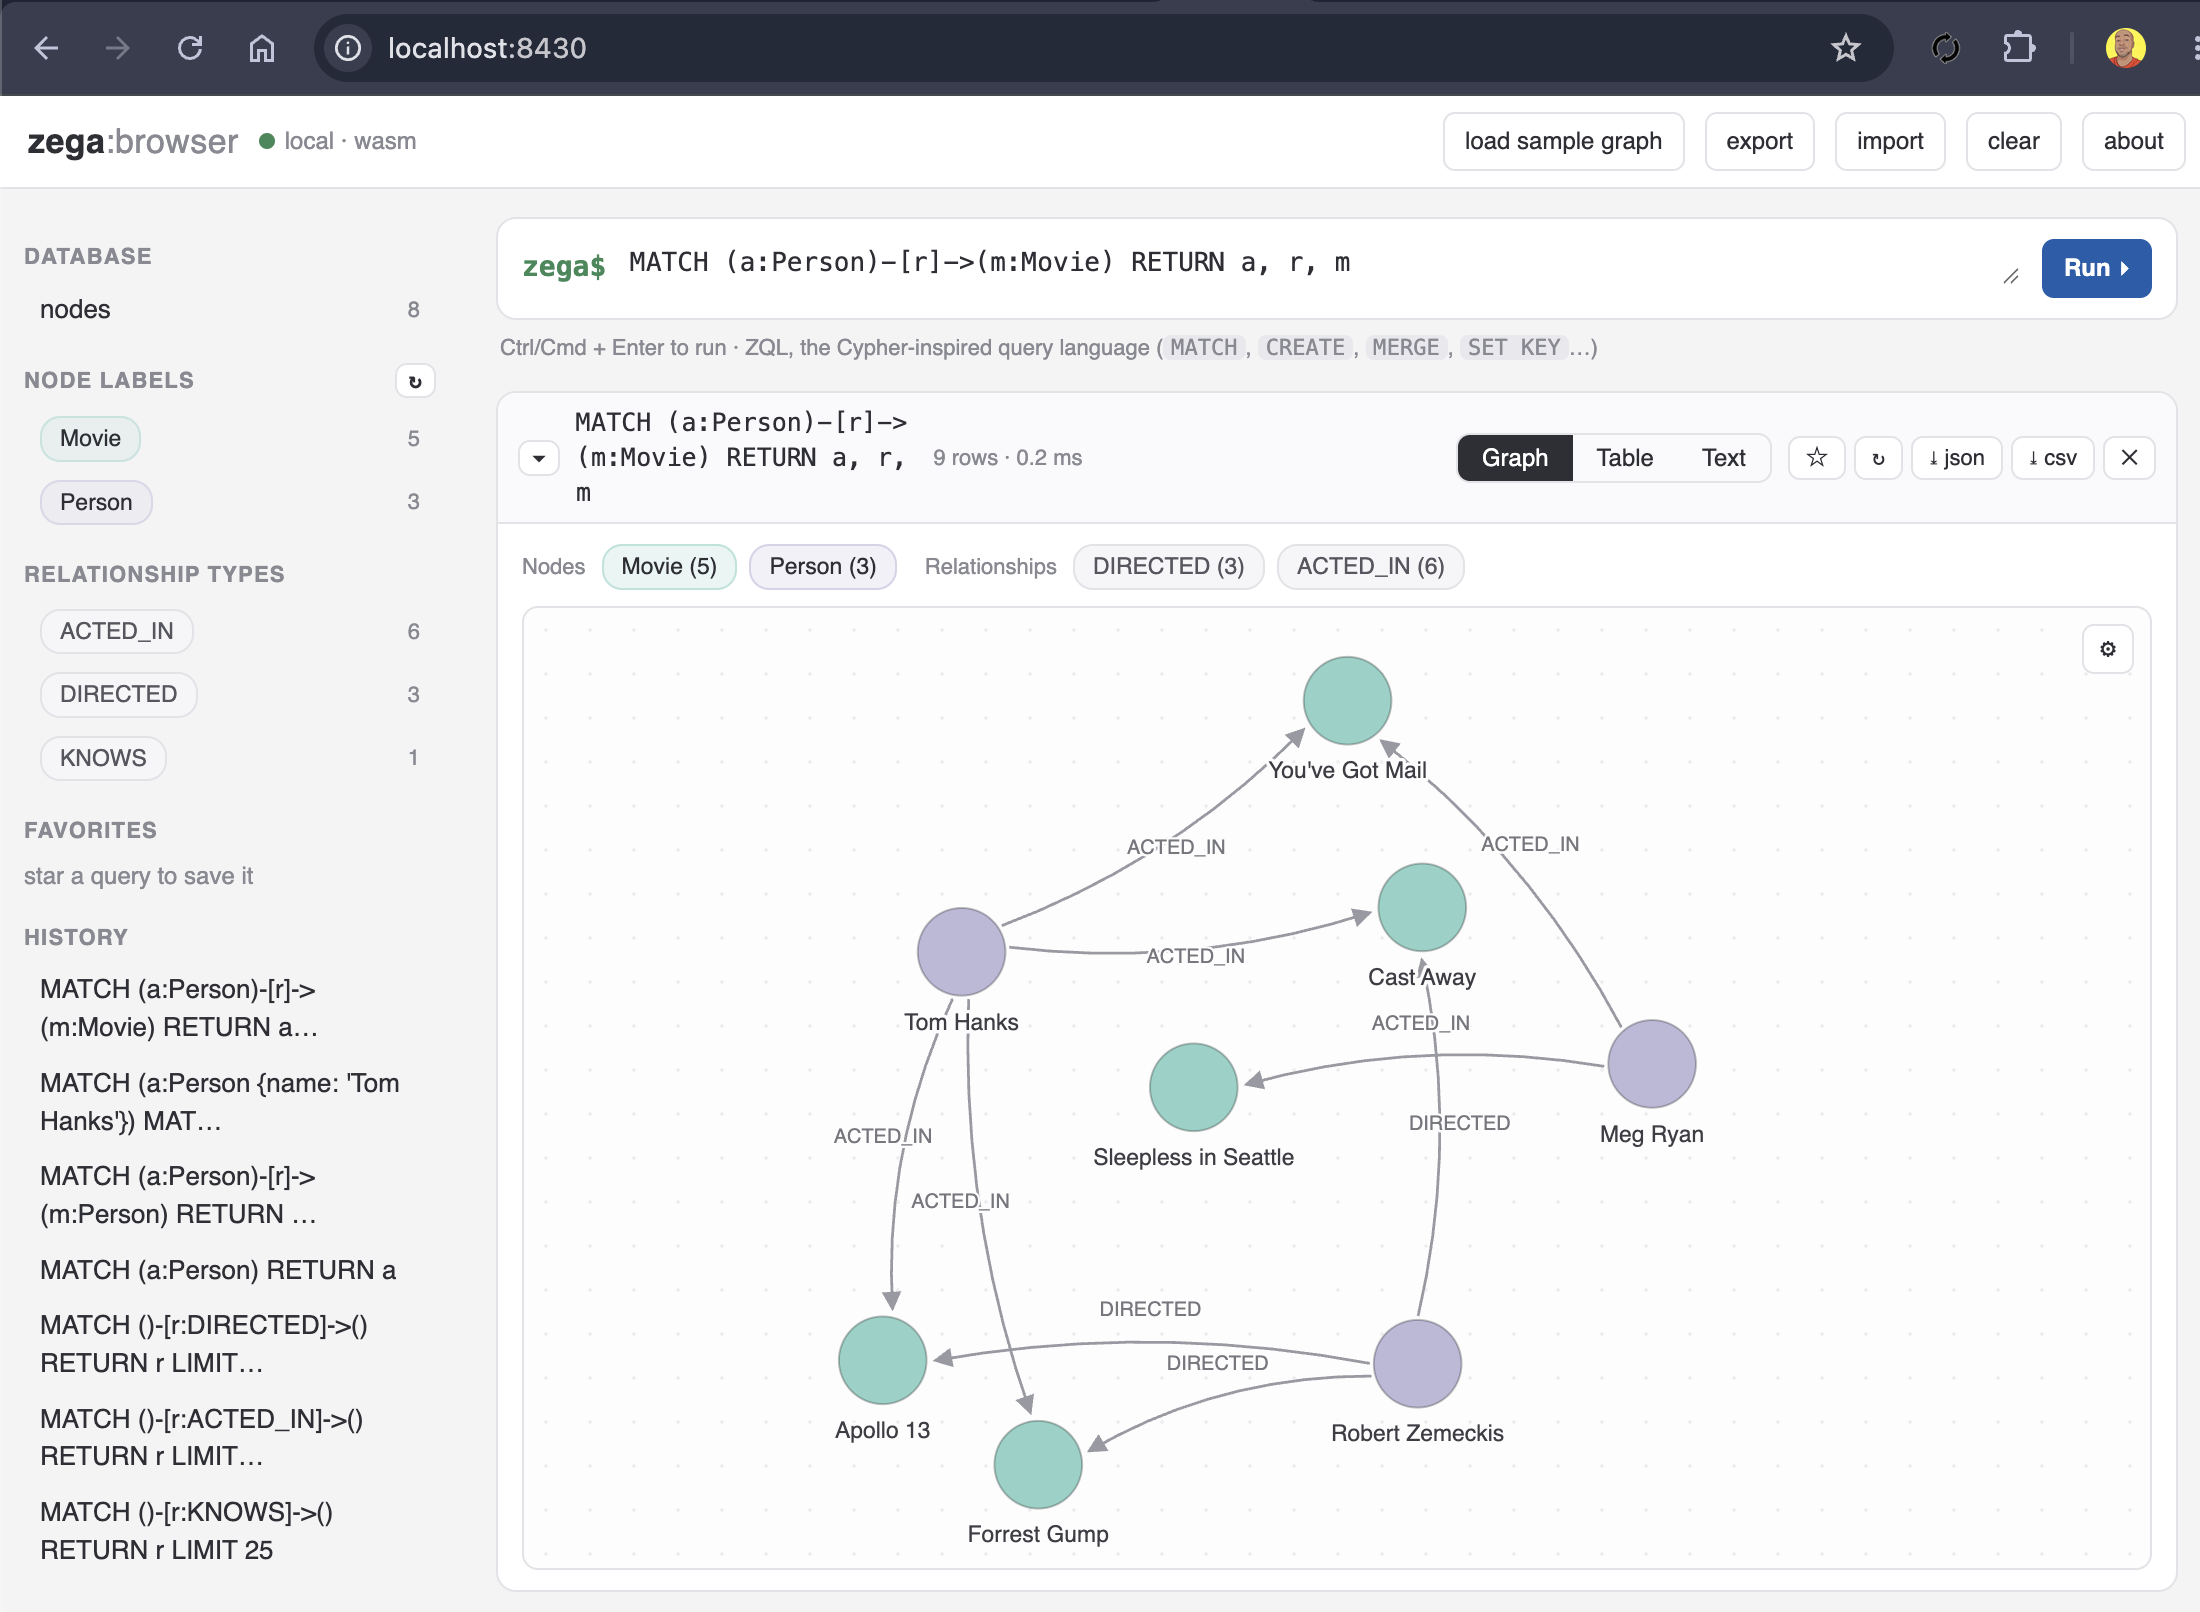
zega provides a property graph with a Cypher-inspired query language in one engine, one binary, one dependency. It runs in-process in any Rust application, persists through a write-ahead log with snapshots, and compiles to WebAssembly for the browser.
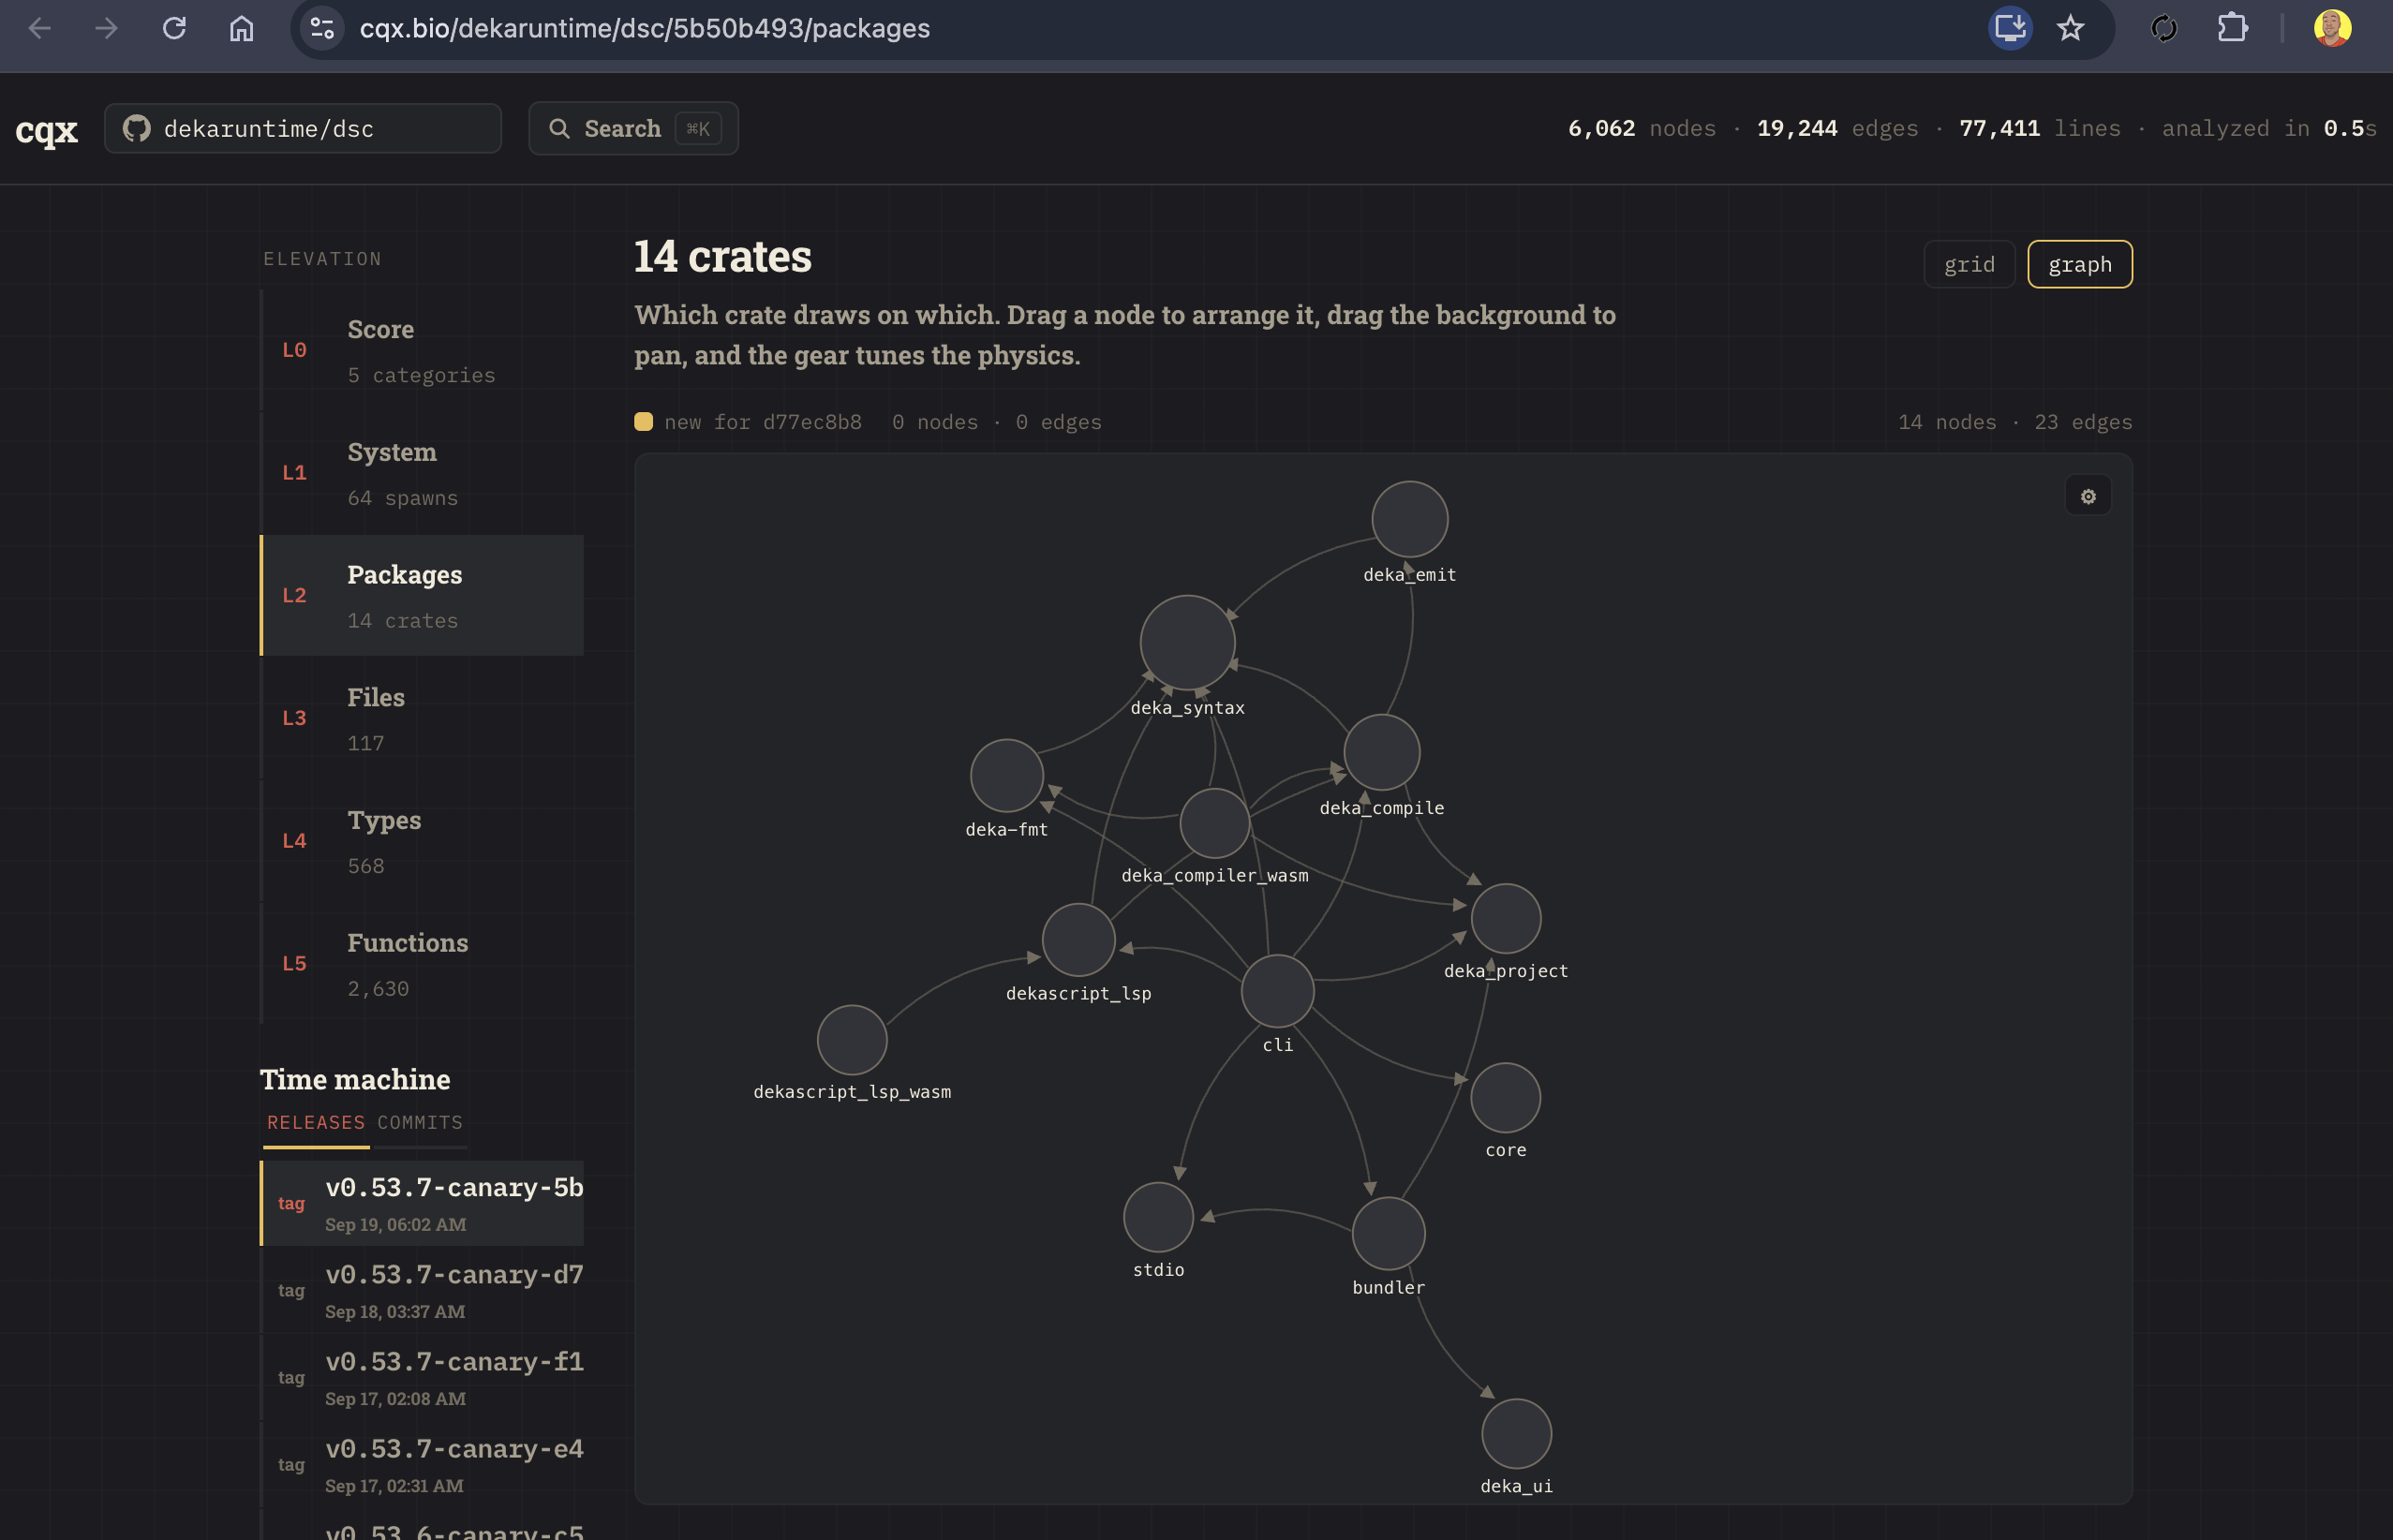
No separate database server to install unless you want one. The server is a single binary that speaks HTTP/JSON. But you can absolutely run it in the browser, just like cqx does for running queries without a server:
Features
- Property graph — labelled nodes, typed relationships, property indexes,
and variable-length traversals (
-[*1..3]->). - Path finding —
road *path -> Junction(name: "B")returns one route with its nodes, edges and cost: fewest edges,by &km(Dijkstra), orby &km toward at(A*, withkm: Float<km>). See paths. - ZQL — a Cypher-inspired query language:
MATCH,CREATE,MERGE,SET,DELETE/DETACH DELETE,WHERE,WITH,UNWIND,FOREACH,ORDER BY/SKIP/LIMIT, aggregates (count,sum,avg,min,max,collect),CASE, and scalar functions. - Embeddable —
zegais a library first. Open a database with two lines of Rust and run graph queries against it. - WebAssembly —
zega-wasmexposes the same engine to JavaScript, in-memory, in the browser. - Durable — CRC32-framed write-ahead log with group commit, torn-write detection, snapshots, and automatic WAL replay on open.
- Optional server — a tokio/axum HTTP server with token auth and ZQL execution on the blocking pool.
- JWT auth + policy engine — HS256/RS256 token verification and row-level access control when you need multi-tenant semantics.
Use the CLI
Build the native executable with cargo build --locked --release -p zega-cli.
The resulting binary is .target/release/zega when using the repository's
CARGO_TARGET_DIR=.target convention (.exe on Windows).
zega --help
zega --version
zega start --data ./data
# http://127.0.0.1:9342
zega explorer --data ./data
# http://127.0.0.1:9343
The CLI locks its data directory for the life of the process; starting another
CLI process against that directory fails instead of sharing the WAL. start defaults to port 9342 (ZEGA on a
phone keypad); explorer defaults to 9343. Both accept --port 0 to ask the
OS for an available port and print the actual URL. The default data directory
is ./zega-data. The explorer serves the embedded browser bundle and uses the
native database for every query, import and graph edit; it never opens a browser
automatically or reseeds an existing database. Its editor currently loads Monaco
from the same CDN used by the standalone explorer, so editor startup needs a
network connection even though the application assets and wasm are embedded.
zega start --host 0.0.0.0 --token-file ./token --data ./data enables an
explicit remote bind. The file must contain one nonempty bearer token (a final
newline is fine). With a token file, every database route requires
Authorization: Bearer <token>, including /health. Without one, only the exact
address 127.0.0.1 is accepted. Explorer always binds to 127.0.0.1.
Configuration is through flags; product behavior does not use environment
variables. The old server executable, environment-variable startup and /cql
route have been removed.
Run ZQL over HTTP
POST /zql accepts { "schema": "...", "query": "..." } and returns
{ "ok": true, "result": ... }. Errors return { "ok": false, "error": "..." }
with an error status. GET /health returns { "ok": true }.
curl -s http://127.0.0.1:9342/zql \
  -H 'Content-Type: application/json' \
  -d '{"schema":"type Player { name: String }","query":"mutation json [\"./players.json\"] { Player(name: $Name) { name } }"}'
curl -s http://127.0.0.1:9342/zql \
  -H 'Content-Type: application/json' \
  -d '{"schema":"type Player { name: String }","query":"{ Player { name } }"}'
Native load paths resolve against the process cwd. HTTP(S) loads use the library
loader. --allow-private-imports explicitly permits private/loopback URLs for
trusted callers; the default rejects them. Browser file-picker imports supply an
optional sources object mapping literal ZQL locations to raw text. The engine
parses and inserts that text. To execute a full ZQL file, set document: true
and put the document in query (no separate schema needed).
The explorer also uses authenticated /graph read/clear and graph edit routes.
Requests execute on the blocking pool under a shared database gate; slow native
loads do not block the HTTP health worker. See data loading
for format, limits and WAL semantics.
Release manifests contain zega-darwin-arm64, zega-darwin-x64, zega-linux-x64
and zega-windows-x64.exe, with SHA-256 hashes. These are the artifact keys
expected by the site's installer.
Use it as a library
Add zega to your Cargo.toml (path or git dependency for now):
use zega::Zega;

// Disk databases replay their WAL on open; in_memory() has the same ZQL API.
let db = Zega::open("./data").build()?;
let schema = "type Person { name: String }";
db.run_lang(schema, r#"mutation { Person(name: "Ada") { name } }"#)?;
let result = db.run_lang(schema, "{ Person { name } }")?;
assert_eq!(result[0]["name"], "Ada");
Durability is configurable on the builder:
let zega = Zega::open("./data")
    .wal_flush_every_write()   // fsync every append
    .wal_flush_interval(10)    // or group-commit every 10 ms
    .traversal_work_budget(1_000_000)
    .build()?;
Embed the engine from npm
The zegadb package is prepared for browser bundlers and Node:
import { createDatabase } from 'zegadb';

const db = await createDatabase();
try {
  console.log(JSON.parse(db.run(
    'type Person { name: String }',
    'mutation { Person(name: "Ada") { name } }',
  )));
} finally {
  db.free();
}
See the package API and bundler notes and
build, consumer checks, and disabled release setup.
Registry publication is pending; local consumers install artifacts/zegadb-0.1.0.tgz.
The repository's own explorer stays in browser/ and uses the WASM crate directly.
Build the raw browser bindings
zega-wasm wraps an in-memory database for JavaScript via wasm-bindgen:
cd zega-wasm
wasm-pack build --target web
import init, { ZegaWasm } from "./pkg/zega_wasm.js";

await init();
const db = new ZegaWasm();

const schema = 'type Person { name: String }';
db.run(schema, 'mutation { Person(name: "Ada") { name } }');
console.log(JSON.parse(db.run(schema, '{ Person { name } }')));
The query language
ZQL has explicit schemas, mutations and graph-shaped queries:
schema {
  type Team { name: String players -> Player[] }
  type Player { name: String salary: Int }
}
mutation csv ["./players.csv"] {
  Team(name: $Team) {
    players -> Player(name: $Name && salary: $Salary) { name salary }
  }
}
query {
  Team {
    name
    players -> Player(salary > 10000000) { name salary }
  }
}
Use run_lang(schema, statement) for one operation or apply_zql(document) for
an entire file. The data-loading guide covers raw sources,
JSON/CSV types and linking. The conformance corpus lives in
zegadb/testsuite.
How persistence works
Every write is appended to a CRC32-framed WAL (wal.bin) — with group
commit by default (5 ms / 64-entry batches) or fsync-per-write if you ask
for it. A statement is all-or-nothing: its writes go to the WAL as one entry,
and until the WAL accepts that entry no reader sees them; if the statement
fails or the WAL refuses it, nothing of it stays in memory or on disk.
Torn writes and bad checksums are detected and truncated on replay.
Zega::snapshot() writes a full snapshot.bin; the next open restores the
snapshot and replays only the WAL after it. Legacy WAL versions are migrated
automatically.
Benchmarks
zega-bench runs the same workloads against zega (embedded) and
Neo4j (Bolt) side by side, and commerce-bench runs a commerce-shaped
graph (10k users, 5k products, 50k orders):
cargo run --release -p zega-bench -- zega
cargo run --release -p zega-bench -- neo4j   # needs neo4j on localhost:7687
cargo run --release -p zega-bench --bin commerce-bench
Workspace layout
zega is the only published crate — the whole engine (query execution,
planner, JWT, policies, WAL, graph storage, ZQL parser and language) lives
inside it as private modules. Everything else in this workspace is a
consumer that depends on zega by path and is never published:
| Crate | What it is |
|---|---|
zega |
the database: the only thing on crates.io |
zega-server |
reusable ZQL HTTP service |
zega-cli |
zega start and the embedded zega explorer |
zega-wasm |
wasm-bindgen wrapper for the browser (in-memory) |
zega-bench |
benchmarks against Neo4j |
Status
zega is early (0.1.0). The engine, query language, WAL, server, and wasm wrapper are functional and tested; the wire protocol is HTTP/JSON only (no Bolt compatibility yet), and there is no REPL.
License
Apache-2.0. See LICENSE.
ZQL uses @ for language-owned names and & for user edge fields. See
Names in ZQL (APS 6) for the complete syntax inventory and migration rules.
zega database
Tags
No tags available
Languages
zega
An embeddable graph database. Written in Rust.
zega provides a property graph with a Cypher-inspired query language in one engine, one binary, one dependency. It runs in-process in any Rust application, persists through a write-ahead log with snapshots, and compiles to WebAssembly for the browser.
No separate database server to install unless you want one. The server is a single binary that speaks HTTP/JSON. But you can absolutely run it in the browser, just like cqx does for running queries without a server:
Features
- Property graph — labelled nodes, typed relationships, property indexes,
and variable-length traversals (
-[*1..3]->). - Path finding —
road *path -> Junction(name: "B")returns one route with its nodes, edges and cost: fewest edges,by &km(Dijkstra), orby &km toward at(A*, withkm: Float<km>). See paths. - ZQL — a Cypher-inspired query language:
MATCH,CREATE,MERGE,SET,DELETE/DETACH DELETE,WHERE,WITH,UNWIND,FOREACH,ORDER BY/SKIP/LIMIT, aggregates (count,sum,avg,min,max,collect),CASE, and scalar functions. - Embeddable —
zegais a library first. Open a database with two lines of Rust and run graph queries against it. - WebAssembly —
zega-wasmexposes the same engine to JavaScript, in-memory, in the browser. - Durable — CRC32-framed write-ahead log with group commit, torn-write detection, snapshots, and automatic WAL replay on open.
- Optional server — a tokio/axum HTTP server with token auth and ZQL execution on the blocking pool.
- JWT auth + policy engine — HS256/RS256 token verification and row-level access control when you need multi-tenant semantics.
Use the CLI
Build the native executable with cargo build --locked --release -p zega-cli.
The resulting binary is .target/release/zega when using the repository's
CARGO_TARGET_DIR=.target convention (.exe on Windows).
zega --help
zega --version
zega start --data ./data
# http://127.0.0.1:9342
zega explorer --data ./data
# http://127.0.0.1:9343
The CLI locks its data directory for the life of the process; starting another
CLI process against that directory fails instead of sharing the WAL. start defaults to port 9342 (ZEGA on a
phone keypad); explorer defaults to 9343. Both accept --port 0 to ask the
OS for an available port and print the actual URL. The default data directory
is ./zega-data. The explorer serves the embedded browser bundle and uses the
native database for every query, import and graph edit; it never opens a browser
automatically or reseeds an existing database. Its editor currently loads Monaco
from the same CDN used by the standalone explorer, so editor startup needs a
network connection even though the application assets and wasm are embedded.
zega start --host 0.0.0.0 --token-file ./token --data ./data enables an
explicit remote bind. The file must contain one nonempty bearer token (a final
newline is fine). With a token file, every database route requires
Authorization: Bearer <token>, including /health. Without one, only the exact
address 127.0.0.1 is accepted. Explorer always binds to 127.0.0.1.
Configuration is through flags; product behavior does not use environment
variables. The old server executable, environment-variable startup and /cql
route have been removed.
Run ZQL over HTTP
POST /zql accepts { "schema": "...", "query": "..." } and returns
{ "ok": true, "result": ... }. Errors return { "ok": false, "error": "..." }
with an error status. GET /health returns { "ok": true }.
curl -s http://127.0.0.1:9342/zql \
  -H 'Content-Type: application/json' \
  -d '{"schema":"type Player { name: String }","query":"mutation json [\"./players.json\"] { Player(name: $Name) { name } }"}'
curl -s http://127.0.0.1:9342/zql \
  -H 'Content-Type: application/json' \
  -d '{"schema":"type Player { name: String }","query":"{ Player { name } }"}'
Native load paths resolve against the process cwd. HTTP(S) loads use the library
loader. --allow-private-imports explicitly permits private/loopback URLs for
trusted callers; the default rejects them. Browser file-picker imports supply an
optional sources object mapping literal ZQL locations to raw text. The engine
parses and inserts that text. To execute a full ZQL file, set document: true
and put the document in query (no separate schema needed).
The explorer also uses authenticated /graph read/clear and graph edit routes.
Requests execute on the blocking pool under a shared database gate; slow native
loads do not block the HTTP health worker. See data loading
for format, limits and WAL semantics.
Release manifests contain zega-darwin-arm64, zega-darwin-x64, zega-linux-x64
and zega-windows-x64.exe, with SHA-256 hashes. These are the artifact keys
expected by the site's installer.
Use it as a library
Add zega to your Cargo.toml (path or git dependency for now):
use zega::Zega;

// Disk databases replay their WAL on open; in_memory() has the same ZQL API.
let db = Zega::open("./data").build()?;
let schema = "type Person { name: String }";
db.run_lang(schema, r#"mutation { Person(name: "Ada") { name } }"#)?;
let result = db.run_lang(schema, "{ Person { name } }")?;
assert_eq!(result[0]["name"], "Ada");
Durability is configurable on the builder:
let zega = Zega::open("./data")
    .wal_flush_every_write()   // fsync every append
    .wal_flush_interval(10)    // or group-commit every 10 ms
    .traversal_work_budget(1_000_000)
    .build()?;
Embed the engine from npm
The zegadb package is prepared for browser bundlers and Node:
import { createDatabase } from 'zegadb';

const db = await createDatabase();
try {
  console.log(JSON.parse(db.run(
    'type Person { name: String }',
    'mutation { Person(name: "Ada") { name } }',
  )));
} finally {
  db.free();
}
See the package API and bundler notes and
build, consumer checks, and disabled release setup.
Registry publication is pending; local consumers install artifacts/zegadb-0.1.0.tgz.
The repository's own explorer stays in browser/ and uses the WASM crate directly.
Build the raw browser bindings
zega-wasm wraps an in-memory database for JavaScript via wasm-bindgen:
cd zega-wasm
wasm-pack build --target web
import init, { ZegaWasm } from "./pkg/zega_wasm.js";

await init();
const db = new ZegaWasm();

const schema = 'type Person { name: String }';
db.run(schema, 'mutation { Person(name: "Ada") { name } }');
console.log(JSON.parse(db.run(schema, '{ Person { name } }')));
The query language
ZQL has explicit schemas, mutations and graph-shaped queries:
schema {
  type Team { name: String players -> Player[] }
  type Player { name: String salary: Int }
}
mutation csv ["./players.csv"] {
  Team(name: $Team) {
    players -> Player(name: $Name && salary: $Salary) { name salary }
  }
}
query {
  Team {
    name
    players -> Player(salary > 10000000) { name salary }
  }
}
Use run_lang(schema, statement) for one operation or apply_zql(document) for
an entire file. The data-loading guide covers raw sources,
JSON/CSV types and linking. The conformance corpus lives in
zegadb/testsuite.
How persistence works
Every write is appended to a CRC32-framed WAL (wal.bin) — with group
commit by default (5 ms / 64-entry batches) or fsync-per-write if you ask
for it. A statement is all-or-nothing: its writes go to the WAL as one entry,
and until the WAL accepts that entry no reader sees them; if the statement
fails or the WAL refuses it, nothing of it stays in memory or on disk.
Torn writes and bad checksums are detected and truncated on replay.
Zega::snapshot() writes a full snapshot.bin; the next open restores the
snapshot and replays only the WAL after it. Legacy WAL versions are migrated
automatically.
Benchmarks
zega-bench runs the same workloads against zega (embedded) and
Neo4j (Bolt) side by side, and commerce-bench runs a commerce-shaped
graph (10k users, 5k products, 50k orders):
cargo run --release -p zega-bench -- zega
cargo run --release -p zega-bench -- neo4j   # needs neo4j on localhost:7687
cargo run --release -p zega-bench --bin commerce-bench
Workspace layout
zega is the only published crate — the whole engine (query execution,
planner, JWT, policies, WAL, graph storage, ZQL parser and language) lives
inside it as private modules. Everything else in this workspace is a
consumer that depends on zega by path and is never published:
| Crate | What it is |
|---|---|
zega |
the database: the only thing on crates.io |
zega-server |
reusable ZQL HTTP service |
zega-cli |
zega start and the embedded zega explorer |
zega-wasm |
wasm-bindgen wrapper for the browser (in-memory) |
zega-bench |
benchmarks against Neo4j |
Status
zega is early (0.1.0). The engine, query language, WAL, server, and wasm wrapper are functional and tested; the wire protocol is HTTP/JSON only (no Bolt compatibility yet), and there is no REPL.
License
Apache-2.0. See LICENSE.
ZQL uses @ for language-owned names and & for user edge fields. See
Names in ZQL (APS 6) for the complete syntax inventory and migration rules.